
AllRounder.ai

Enrol to start learning

Reading is open to everyone. Enrolling is free, and it is what unlocks the audio lessons, practice tests and progress tracking.
Enrol free
6. Unsupervised Learning – Clustering & Dimensionality Reduction

6. Unsupervised Learning – Clustering & Dimensionality Reduction

Learn about 6. Unsupervised Learning – Clustering & Dimensionality Reduction and discover its key concepts through interactive lessons and practical exercises.

Sections

Unsupervised Learning – Clustering & Dimensionality Reduction

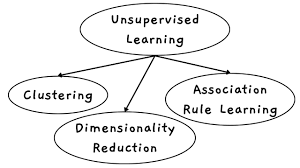
Unsupervised learning seeks to identify hidden patterns in unlabeled data, primarily through clustering and dimensionality reduction techniques.

6 Section Overview

Start current section content and materials

6.1 Clustering

Clustering is the process of grouping similar data points together in unsupervised learning to reveal patterns within datasets.

6.1.1 What is Clustering?

Clustering is the process of grouping similar data points into clusters based on their features.

6.1.2 Types of Clustering Algorithms

This section discusses various clustering algorithms used in unsupervised learning, including K-Means, Hierarchical Clustering, and DBSCAN.

6.1.2.1 K-Means Clustering

K-Means Clustering is a centroid-based algorithm that partitions a dataset into K clusters, aiming to group similar data points by minimizing the within-cluster sum of squares.

6.1.2.2 Hierarchical Clustering

Hierarchical clustering is a technique that organizes data points into a tree structure based on their similarity, allowing for various levels of granularity in cluster analysis.

6.1.2.3 DBSCAN (Density-Based Spatial Clustering of Applications with Noise)

DBSCAN is a clustering algorithm that groups data points based on their density, distinguishing between core points, border points, and noise.

6.1.3 Cluster Evaluation Metrics

Cluster evaluation metrics help assess the quality of clustering algorithms.

6.2 Dimensionality Reduction

Dimensionality Reduction techniques are used to simplify datasets by reducing the number of features while retaining essential patterns, enhancing computational efficiency and visualization.

6.2.1 Why Reduce Dimensions?

Reducing dimensions in data sets helps mitigate issues such as the curse of dimensionality and enhances visualization and computational efficiency.

6.2.2 Principal Component Analysis (PCA)

Principal Component Analysis (PCA) is a linear transformation technique that reduces dimensionality by transforming original features into a new set of uncorrelated variables called principal components, capturing maximum variance.

6.2.3 t-SNE (t-Distributed Stochastic Neighbor Embedding)

t-SNE is a non-linear dimensionality reduction technique used for visualizing high-dimensional data while preserving local structure.

6.2.4 UMAP (Uniform Manifold Approximation and Projection)

UMAP is an innovative technique for dimensionality reduction that maintains the local and global structure of data effectively.

6.3 Applications of Clustering & Dimensionality Reduction

Clustering and dimensionality reduction are vital techniques in unsupervised learning used in various applications to uncover patterns and simplify data.

6.4 Chapter Summary

The chapter presents an overview of unsupervised learning, focusing on clustering and dimensionality reduction techniques to uncover hidden patterns in unlabeled data.

Learning Objectives

  • Master the fundamentals of 6. Unsupervised Learning – Clustering & Dimensionality Reduction

  • Apply learned concepts in practical scenarios

  • Successfully complete all chapter exercises

Practice Exercises

Total Questions

3

Estimated Time

6 min

Passing Score

70%

Instructions

  • Read each question carefully
  • You can use hints if you need help
  • Complete all questions before submitting